JavaScript SEO is the work of making a JavaScript-powered website discoverable, renderable and understandable to search engines. The main checks are what the server returns, what appears after scripts run, how routes and links behave, whether metadata remains consistent and what happens when an API, resource or hydration step fails.
Google can render JavaScript. That does not make every JavaScript implementation equally dependable. A server-rendered React site, static Astro page, browser-only application and AI-generated single-page app can all use JavaScript while presenting very different crawling and indexing conditions.
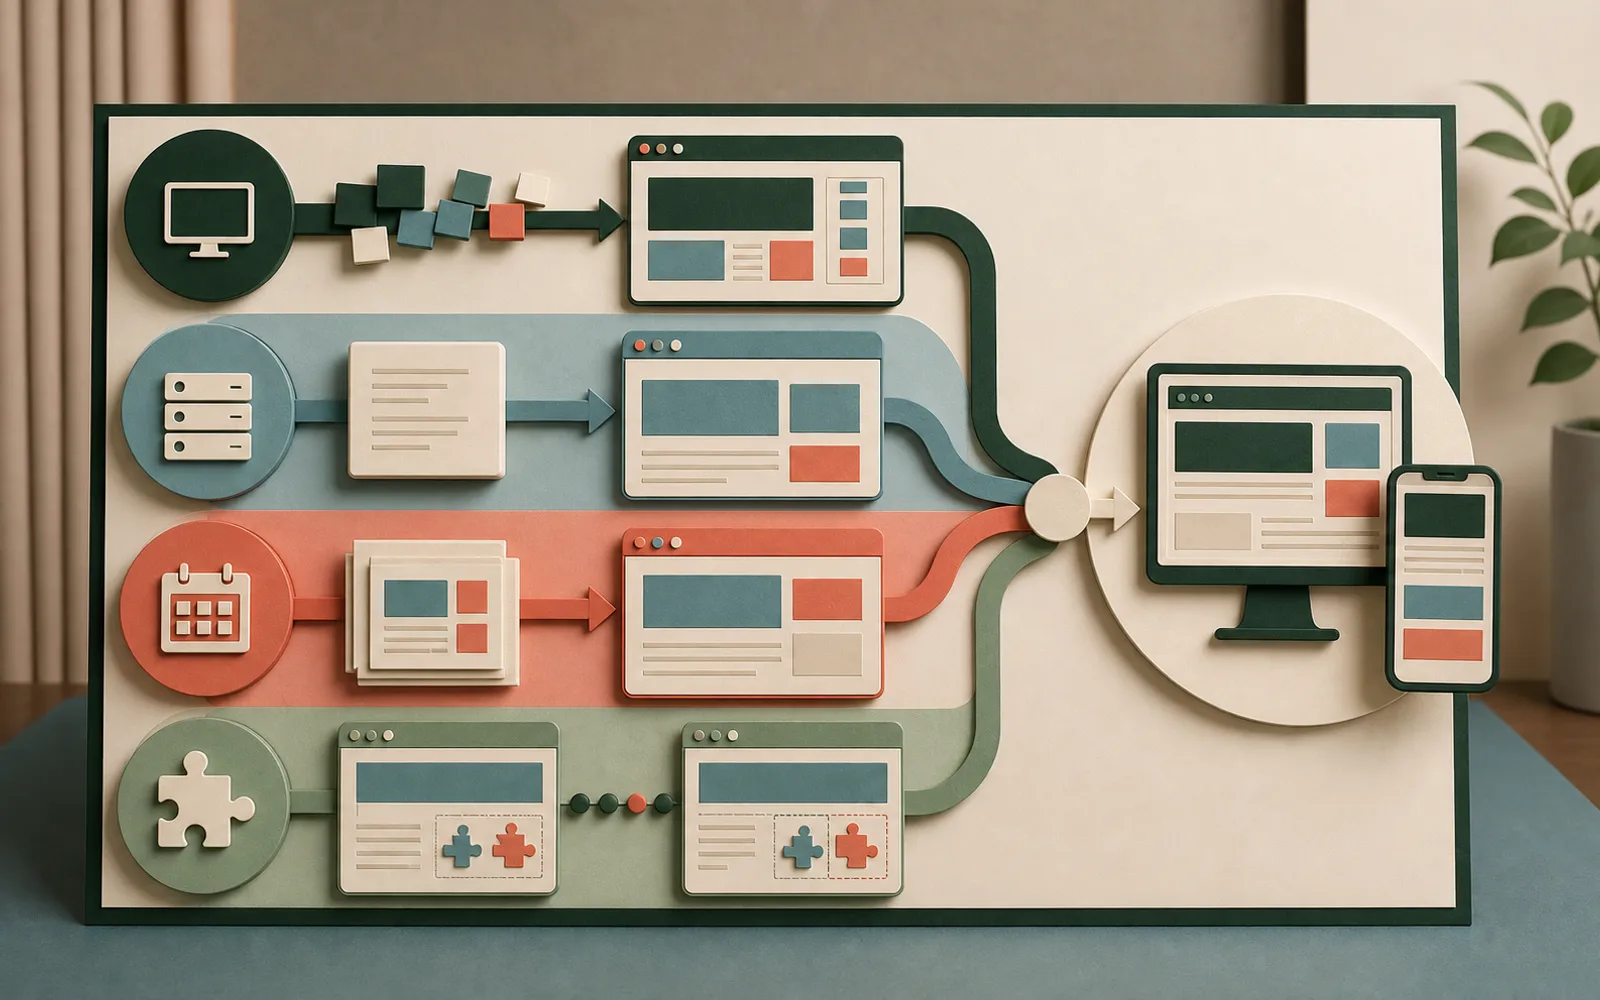
JavaScript rendering approaches at a glance
Approach | What the server sends | Main advantage | Main SEO consideration | Typical fit |
|---|---|---|---|---|
Client-side rendering (CSR) | Application shell plus scripts | Highly interactive application workflow | Essential content waits for successful browser rendering | Authenticated tools and application interfaces |
Server-side rendering (SSR) | Page HTML generated for the request | Fresh content in the response | Server reliability, caching and response time matter | Personalised or frequently changing public pages |
Static site generation (SSG) | Prebuilt HTML files | Fast, resilient delivery with immediate content | Publishing must rebuild or revalidate changed pages | Marketing pages, blogs and documentation |
Hybrid or islands | Static or server HTML plus selected interactive components | JavaScript is limited to where it adds value | Each route and component still needs explicit testing | Mixed marketing and interactive sites |
There is no universal winner. A product dashboard may need client-side state that a service page does not. The practical goal is to provide useful HTML early, add interaction deliberately and preserve correct URLs and responses throughout.
What the server sends versus what the browser renders
Request a URL and inspect the response before opening developer tools. The server decides the status code, headers and initial HTML. That response may already contain the title, canonical, headings, copy and links. Alternatively, it may contain a root element and references to scripts that create the page later.
The browser parses the HTML, loads resources, runs JavaScript and produces a rendered DOM. Client-side data requests may add content after the first render. Hydration may attach event handlers to HTML that the server already produced.
Google's JavaScript SEO basics describe crawling, rendering and indexing as separate phases. Googlebot extracts links from the response, queues eligible pages for rendering and examines the rendered output again. The documentation notes that server rendering or pre-rendering remains useful for people and crawlers, and that not every bot can run JavaScript.
Inspecting only “view source” can miss content that Google may render. Inspecting only the visual browser can miss a weak initial response and the failures that occur before the page appears. JavaScript SEO needs both views.
Client-side rendering, server rendering and static generation
Client-side rendering
A CSR application normally sends a small shell. JavaScript identifies the route, fetches data and builds the visible interface. This can be appropriate for logged-in software where search indexation is irrelevant.
For public content, CSR adds dependencies. The crawler needs the scripts and APIs to succeed, the route must resolve directly and the rendered DOM must contain the intended content. Slow or failed resources can delay or remove what becomes indexable.
CSR is not automatically bad for SEO. It simply needs stronger rendering and failure tests when public discovery matters.
Server-side rendering
SSR creates HTML on the server for a request. Search engines and visitors receive meaningful content immediately, while the browser can hydrate the page for interaction. SSR handles fresh or personalised content without waiting for a full static rebuild.
The server path becomes operationally important. A slow data source can delay the response, an exception can produce an error page and incorrect caching can serve stale material. Status codes and fallbacks must remain accurate.
Static site generation
SSG creates HTML during a build and serves the resulting files through a host or content-delivery network. It is a strong fit for pages that change through controlled publishing: service pages, landing pages, articles, categories and authors.
The main question becomes freshness. A CMS publish event must rebuild, revalidate or otherwise update affected output. Keep the last successful build available if new content fails validation. Static does not have to mean manually edited; it describes delivery, not the editorial workflow.
Hybrid rendering and islands
Hybrid frameworks can render each route differently. A marketing page may be static, a product listing server-rendered and an account area client-rendered. Islands architecture keeps most of a page as HTML and hydrates selected interactive components.
This often gives a sensible balance, but the flexibility needs a route inventory. Teams should know which pages are indexable, how each is generated and what invalidates the cached or static result.
Hydration in plain English
Hydration is the browser process that attaches JavaScript behaviour to server-generated HTML. The visitor can see the initial content before hydration completes, then menus, forms and other components become interactive.
A mismatch occurs when the browser expects different markup from what the server sent. Causes include time-dependent output, random IDs, browser-only data, locale differences and stale deployments. Frameworks may warn, replace parts of the DOM or fail to attach behaviour.
From an SEO perspective, visible server HTML is useful, but a broken menu or form remains a user and quality problem. Test the console, keyboard interaction and error reporting. Slow the network and block one script to see whether essential navigation still works.
Discovery, routes and internal links
Google's crawlable-link guidance says an ordinary <a> element with an href is the dependable form. Scripted click handlers on a div or span do not provide the same discovery or keyboard behaviour.
Check navigation before and after hydration. Links should point to canonical URLs and work when opened in a new tab. Infinite scroll and “load more” interfaces need paginated, linked URLs when all items should be crawlable.
A direct request to every public route should return the intended page. Do not configure a host to return the same application shell with 200 for every missing path. That creates soft errors and makes monitoring less reliable. Use permanent redirects for moved pages, 404 for unknown routes and 410 when content was deliberately removed with no replacement.
Robots rules and sitemaps do different jobs. robots.txt manages crawling; it is not a dependable removal mechanism. The XML sitemap should contain absolute canonical URLs that are public and intended for search. It should not include drafts, redirects or authenticated views.
Metadata, canonicals and structured data
Client-side route changes must update the title, description, canonical and social metadata correctly. Test a direct request as well as in-app navigation. A route can appear correct after clicking from the homepage but deliver default metadata when opened directly.
Google recommends a clear canonical in HTML source when possible. Its canonical guidance warns against specifying one value initially and changing it to another with JavaScript. Internal links and sitemap URLs should agree with the preferred version.
JSON-LD may be generated with JavaScript, and Google can process it. The structured-data guidance says to test the rendered implementation. Markup must describe visible content and meet the specific type's rules.
Lazy loading without hidden content
Lazy loading images below the fold is normally useful. Provide width and height so the page does not jump, and use real image elements with appropriate alternatives. Do not require scrolling, hovering or clicking before essential article copy or internal links enter the DOM.
Googlebot does not interact like a person with every control. Content that appears only after an intersection observer fires or an infinite list advances can remain undiscovered. Test the rendered DOM without manually exercising the page.
Common JavaScript SEO failure modes
Symptom | Likely cause | Test | Practical fix |
|---|---|---|---|
Blank or thin source HTML | Browser-only rendering | Request the URL without scripts | Pre-render or server-render indexable content |
Correct homepage, missing deep routes | Hosting fallback or router mismatch | Open each URL directly | Configure route-aware generation and true errors |
Links not found by crawler | Script-only click targets | Inspect anchor markup | Use <a href> for navigable destinations |
Wrong titles after direct load | Metadata set only during navigation | Compare direct and in-app visits | Generate route-specific head data on the server or build |
Conflicting canonicals | Server and client set different values | Compare source and rendered head | Set one stable canonical and link to it consistently |
Content disappears during rendering | API or JavaScript failure | Block the request and inspect errors | Render a useful fallback and monitor failures |
Interaction fails although copy is visible | Hydration mismatch | Check console and use keyboard | Make server and client output deterministic |
Images absent from rendered inspection | Custom lazy loader waits for interaction | Inspect without scrolling | Use native loading or crawler-accessible fallbacks |
Every unknown route returns 200 | Catch-all application shell | Request invented URLs | Return real 404 or 410 statuses |
How to test a JavaScript website
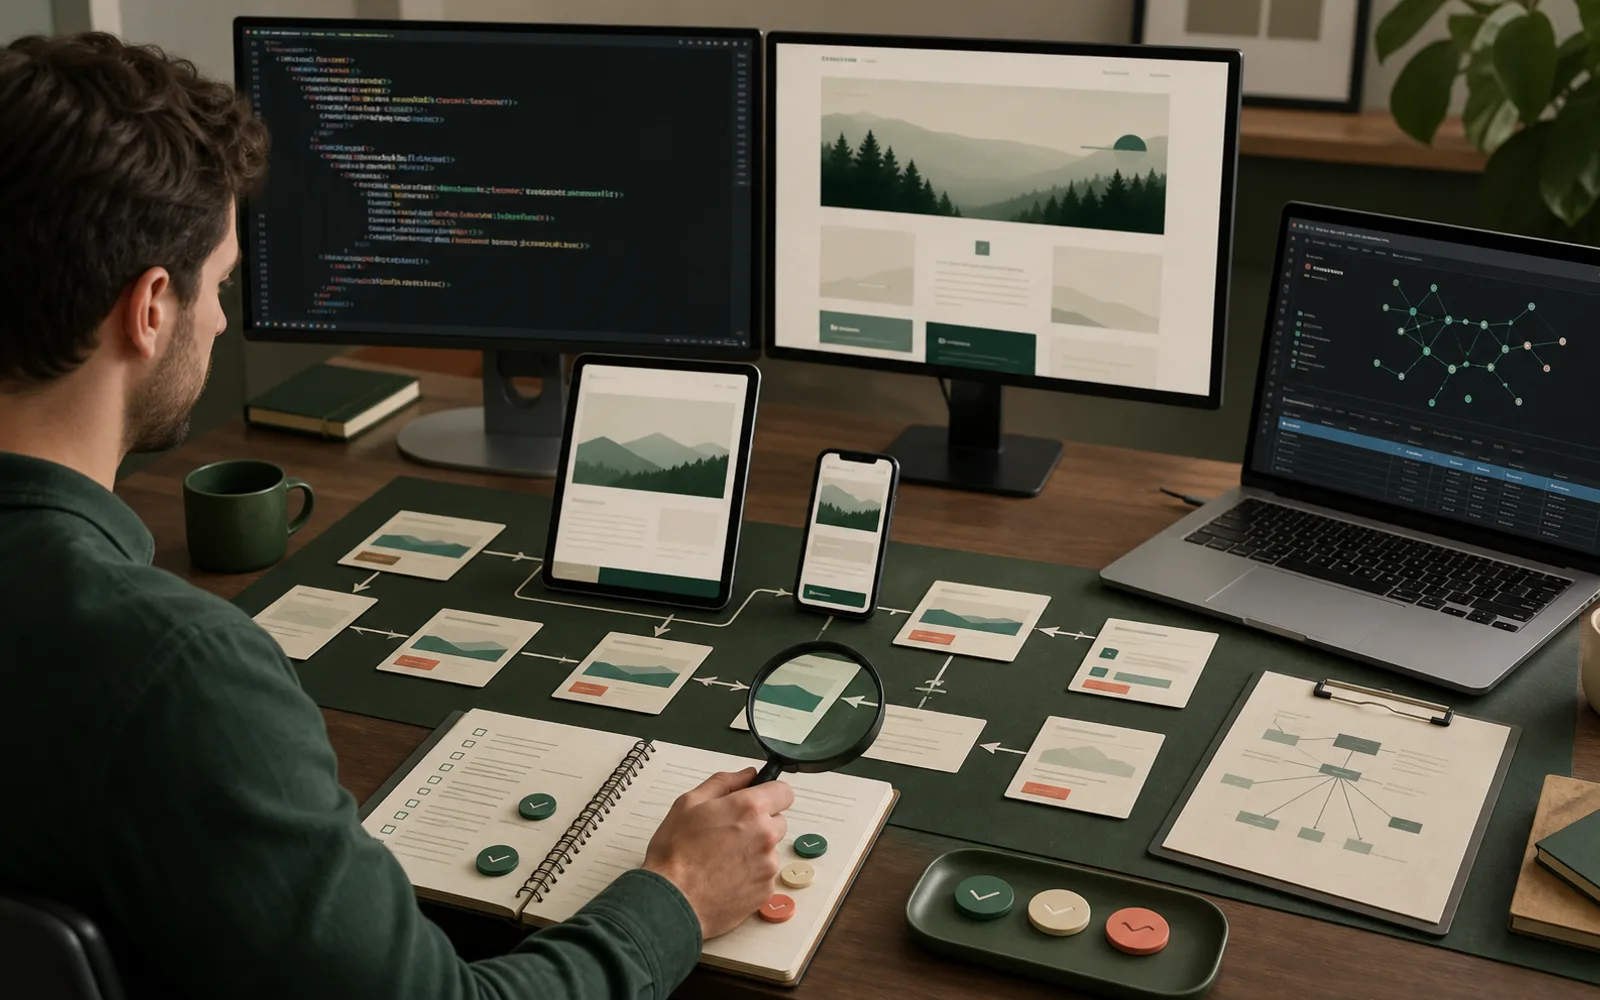
Start with a route list: homepage, each public template, pagination, a redirect, a removed page, a missing URL and any private boundary. Test the deployed production build rather than only the development server.
Request each URL and record status, redirects, headers and response HTML.
Compare source HTML with the rendered DOM after scripts complete.
Review console errors, failed resources and delayed API requests.
Crawl once with rendering disabled and once with rendering enabled.
Compare discovered URLs, titles, canonicals, headings and main content.
Inspect important pages with Search Console URL Inspection.
Test the Rich Results output against the visible page.
Navigate by keyboard and open links in new tabs.
Slow or block scripts and APIs to inspect graceful fallbacks.
Repeat after a production deploy, framework upgrade or routing change.
Google's inspection reflects its own rendering path, while a general crawler helps identify patterns at scale. Browser testing catches interaction defects. None replaces the others.
Practical fixes by problem
Do not rebuild the entire stack because one page has a rendering issue. Match the fix to the failure.
Public copy is absent until a fetch completes: render it during the build or request, or provide a server response with the essential content.
A client router hides route errors: configure the hosting layer and framework to return real responses for every path.
Navigation uses click handlers: replace navigable controls with semantic anchors and preserve normal link behaviour.
Metadata changes inconsistently: centralise route metadata and produce it in source HTML where possible.
Hydration replaces approved content: remove non-deterministic rendering and pass consistent server data to the client.
Lazy content is missing: use native lazy loading for media and render crawlable text and links without interaction.
Rendering is slow: reduce script and data work, cache appropriate responses and pre-render stable routes.
CMS updates appear late: connect publishing to targeted rebuild or revalidation and monitor failures.
The right solution may be CSR, SSR, SSG or a hybrid. The pass condition is dependable output and behaviour, not loyalty to one architecture.
Pre-launch JavaScript SEO checklist
Maintain an indexation map for every public and private route.
Confirm direct requests return the correct content and status.
Put essential copy, links and metadata into source or reliably rendered HTML.
Use ordinary anchor links with canonical destinations.
Keep one route-specific title, H1 and canonical.
Make source and rendered canonicals agree.
Validate structured data against visible content.
Keep important text and links out of interaction-only lazy components.
Compare non-rendered and rendered crawl results.
Test scripts, APIs and hydration failure states.
Exclude private, duplicate and redirect URLs from the sitemap.
Inspect priority pages in Search Console after deployment.
Monitor runtime errors, status changes and content freshness.
Why Elkwood checks rendered output
Elkwood's public marketing and editorial pages are built to produce static HTML, with JavaScript reserved for interactions that need it. That reduces the rendering burden for core copy and links. We still inspect the deployed result because an intended architecture is not evidence that every route, canonical or publish event works.
Our service checks cover titles, descriptions, headings, internal links, sitemap membership, robots rules, structured data, status codes, responsive layouts and performance. It creates an SEO-ready foundation, not a ranking promise. What Elkwood includes and the pricing are published.
For the wider AI question, see whether AI-built websites are good for SEO. The AI website production workflow covers the steps before and after technical rendering.
Sources checked
Google JavaScript SEO basics, checked 26 August 2026.
Google troubleshooting for JavaScript Search issues, checked 26 August 2026.
Google crawlable-link guidance, checked 26 August 2026.
Google URL structure guidance, checked 26 August 2026.
Google sitemap guidance, checked 26 August 2026.
Google canonical URL guidance, checked 26 August 2026.
Google structured data with JavaScript, checked 26 August 2026.
Google structured-data guidelines, checked 26 August 2026.
Quick answers
Frequently asked questions
Can Google crawl JavaScript?
Yes. Google can render JavaScript and inspect the resulting DOM. Crawling, rendering and indexing are separate stages, so test both the response and rendered output.
What is server-side rendering for SEO?
Server side rendering creates page HTML on the server for each request or through a cache. It gives crawlers and visitors meaningful content before browser JavaScript runs.
Is client-side rendering bad for SEO?
Not automatically. It adds rendering and data dependencies for public content. If those paths are fast, accessible and tested, CSR pages can be indexed.
What is hydration?
Hydration attaches JavaScript behaviour to HTML that was already generated on the server or at build time. A mismatch can leave visible content but break interactions.
How do I test rendered HTML?
Compare source HTML with the browser DOM, crawl with and without rendering, inspect network and console failures, and use Search Console URL Inspection on the deployed page.
Do internal links need to exist in HTML?
Use ordinary anchors with href destinations in the source or rendered DOM. Avoid relying on script only click handlers for pages that search engines should discover.