Yes, AI-built websites can be good for SEO and can rank in Google. Using AI to help create the design or code is not, by itself, the problem. The outcome depends on the published site: useful content, crawlable pages, correct HTML and status codes, clear internal links, sound metadata, good performance and an implementation that search engines can render reliably.
AI can also produce poor SEO output quickly. A polished preview may hide empty initial HTML, broken routes, duplicated copy, invented expertise, oversized images or structured data that does not match the visible page. Test what went live rather than accepting the method or product label as proof.
What determines whether an AI website is SEO-ready?
Important content is present in the initial or reliably rendered HTML.
Public pages return meaningful 200, redirect, 404 or 410 status codes.
Navigation and contextual links use real anchor elements with href destinations.
Every indexable page has a useful title, H1, canonical and distinct purpose.
Robots rules permit required pages and resources to be crawled.
The XML sitemap lists absolute canonical URLs that should appear in search.
Structured data is valid and represents content visitors can see.
Images, fonts and scripts do not make the experience unnecessarily slow or unstable.
Copy is accurate, original enough to be useful and reviewed by a responsible person.
The live domain is tested in Search Console, not only in a local preview.
No single item guarantees rankings. Together they establish that the site can compete on its content and reputation rather than being undermined by its implementation.
What search engines actually receive
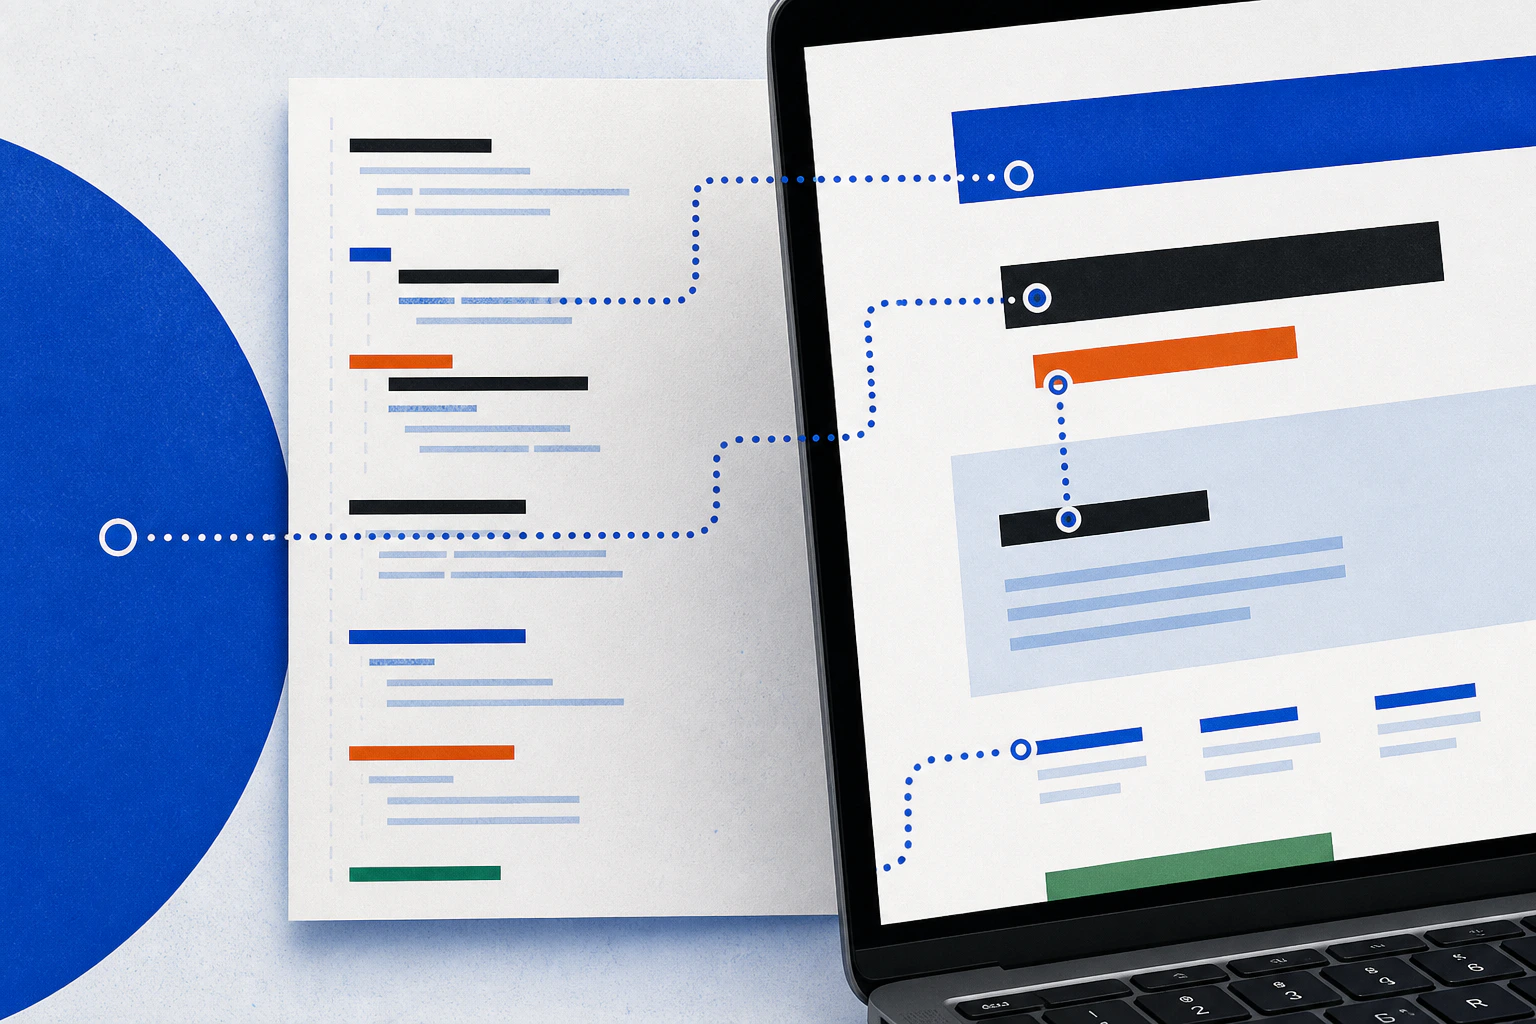
When Googlebot requests a page, the server returns an HTTP response. That response includes a status code, headers and usually HTML. Google can extract metadata, content and links from that initial HTML. If the page depends on JavaScript, Google may queue it for rendering and inspect the resulting DOM later.
Google's JavaScript SEO documentation describes crawling, rendering and indexing as separate phases. A 200 response can enter the rendering queue, while a non-200 response may be skipped. The documentation also says server-side rendering or pre-rendering remains a useful idea because it is faster for people and crawlers, and not every bot can execute JavaScript.
This is why a browser screenshot is incomplete evidence. The page can look correct after scripts run on a fast laptop while the response contains little more than an empty application shell. That may still be indexable by Google, but it creates more dependencies and gives other search, social and AI crawlers less useful material.
Crawlability and internal links
Important pages should be reachable through ordinary navigation or contextual links. Google says it can generally crawl a link when it is an <a> element with an href that resolves to a real web address. A clickable card implemented only with a script event or a span is a weaker foundation.
Test the menu, footer, breadcrumbs, category pages and article links. Every important URL should have at least one useful path from another public page. Anchor text should describe the destination naturally. Do not rely on an XML sitemap to compensate for an isolated page.
Robots controls need separate review. robots.txt controls crawling, not reliable removal from the index. A noindex directive belongs on a page that should not appear in results, but Google must be able to crawl that page to see the directive. Preview and admin routes should be protected properly rather than merely omitted from the menu.
The sitemap should contain fully qualified canonical URLs and exclude drafts, private routes, redirects and known error pages. Google's current sitemap guidance describes sitemaps as a discovery mechanism, not an indexing guarantee.
Rendering, routing and hydration
AI-assisted coding tools often generate single-page applications because they provide fast interactive previews. That architecture can work for SEO, but route and rendering behaviour must be deliberate.
Client-side rendering
In a purely client-rendered site, the server may return a small shell and JavaScript fetches or constructs the visible content. Google can process many such pages, but rendering adds another stage. A blocked script, failed API request or runtime error can leave the crawler with little useful content.
Static generation and server rendering
Static generation places the page content into HTML during a build. Server-side rendering creates HTML for each request or through a caching layer. Both can provide immediate copy, links and metadata while adding JavaScript only where interaction is needed.
Static output is a strong fit for service pages, articles, category pages and other content that changes through controlled publishing. Customer accounts, checkout and live tools can remain dynamic without forcing the entire marketing site into one browser-only application.
Hydration and fallback behaviour
Hydration attaches interactive behaviour to existing HTML. A hydration error may break a menu or form even when the copy remains visible. Test with scripts delayed or failed, then confirm that essential links still work and errors are reported.
Client-side routers must also serve real URLs. A direct request to /services/web-design/ should return that page, not a generic shell with a false 200 for every path. Missing pages should return a true 404, and moved pages should use a permanent redirect.
On-page metadata and canonical URLs
Every indexable page needs a descriptive title and a visible H1 that accurately summarise its purpose. The meta description can help explain the page in search results, although Google may choose a different snippet. Headings should structure the content for people rather than repeat keyword variations mechanically.
Canonical URLs are particularly important when generators produce preview parameters, duplicated paths or several URL versions. Google's canonical guidance recommends a self-referential canonical and consistent internal links to the preferred URL. For JavaScript sites, Google says the clearest approach is to place the canonical in source HTML and avoid changing it to a different value later.
Check social metadata as well. Open Graph and related tags do not create rankings, but accurate titles, descriptions and images improve how approved pages appear when shared.
Structured data must match the visible page
Structured data can help search engines understand entities and make a page eligible for particular search features. It is not a shortcut to authority and does not guarantee a rich result.
Use the most specific appropriate type, include the required properties and represent the visible content. Do not add FAQ, review, product or author details that visitors cannot see. Google's structured-data guidelines state that hidden, misleading or irrelevant markup can lose rich-result eligibility and may be treated as spam.
Validate the generated JSON-LD, then inspect the live URL. Templating and deployment can break schema that worked in a local test. Article dates, author URLs, image locations and canonical IDs should all resolve correctly on the public domain.
Content quality and duplication
Google's current guidance does not set a preferred word count. It asks whether content provides original information or analysis, covers the topic substantially, demonstrates relevant experience and leaves the reader satisfied. The people-first content guidance also encourages clear bylines and information about who created the work.
AI can help research, structure and edit material. Google's generative AI content guidance warns that generating many pages without adding value may violate the spam policy on scaled content abuse. That is an output and intent problem, not a blanket ban on assistance.
Common failure modes on AI-built sites include:
near-identical service pages with only the location or keyword changed;
unsupported claims and generic testimonials;
headings written for search phrases rather than readers;
stock FAQs that repeat the main page without adding clarity;
orphan pages created because generation was cheap;
titles and canonicals copied across several routes;
content hidden inside images or interactive elements.
Review the entire site as one information system. Our guide to AI-generated content and SEO covers sourcing, authorship and editorial risk in more detail.
Performance, responsiveness and accessibility
AI-generated design can include large hero images, several typefaces, animation libraries and client-side effects without making the cost visible. Compress and resize images, load only the weights you need, reserve media dimensions and remove scripts that do not help the visitor.
Google's Core Web Vitals measure loading, interaction and visual stability. Current published thresholds define a good experience as LCP within 2.5 seconds, INP at 200 milliseconds or less and CLS at 0.1 or less at the 75th percentile. Test in the lab before launch, then use field data when real visits are available.
Accessibility is not a direct synonym for rankings, but it is part of building a page people can use. Check keyboard navigation, focus, labels, headings, text alternatives, contrast, zoom, reduced motion and form errors. A technically crawlable page can still fail its audience.
How to test an AI-built website for SEO
Question | Practical test | Pass evidence |
|---|---|---|
What is in the initial response? | View source or request the URL without executing scripts | Main copy, title, canonical and useful links are present or intentionally rendered |
What appears after rendering? | Inspect the browser DOM and Search Console rendered HTML | Complete visible content without blocked resources or runtime failures |
Can important pages be discovered? | Crawl the deployed site and inspect internal links | Canonical 200 pages have ordinary linked paths |
Do routes return the right status? | Request live, missing, moved and private URLs | Correct 200, redirect, 404, 410 or access response |
Are pages distinct? | Compare titles, H1s, canonicals and main copy | Each indexable URL has a clear purpose |
Does structured data match? | Run the Rich Results Test and compare with the page | Valid supported markup for visible content |
Is the page usable? | Test mobile, keyboard, forms and zoom | No overflow, blocked journeys or unexplained errors |
Is performance acceptable? | Run a production lab test and monitor field data | No obvious image, script or layout defect; field targets tracked |
Use a crawler and automated audit to find patterns, then inspect representative templates manually. A green score does not prove the copy is useful, and a single failed lab metric does not explain the cause.
AI website SEO launch checklist
Confirm the live preferred domain uses HTTPS and redirects other versions consistently.
Check that every indexable URL returns 200 and every missing URL returns a true error status.
Inspect the initial HTML and rendered DOM on each major template.
Verify one descriptive title, one visible H1 and a self-referential canonical per page.
Crawl navigation, breadcrumbs and contextual links with JavaScript both enabled and constrained.
Remove drafts, previews, admin routes and duplicates from the public sitemap.
Check robots rules and noindex directives against the intended indexation map.
Validate visible Article, Breadcrumb, Product or other appropriate structured data.
Review facts, bylines, sources, dates and repeated copy.
Test mobile layouts, keyboard use, forms, images and error states.
Measure the production build and fix obvious loading or layout instability.
Verify the site in Search Console, submit the sitemap and inspect priority pages.
Monitor indexing, crawl errors, performance and content changes after launch.
What Elkwood checks
Elkwood uses modern assisted production, but our SEO-readiness work is based on the published output. We check static public content, route status, titles, descriptions, canonicals, headings, internal links, sitemap membership, robots controls, structured data, responsive layouts and performance before launch.
That is a foundation, not a promise of rankings. A business still needs useful offers, real expertise, appropriate content and promotion. We state the boundary because “SEO-ready” should describe the site preparation, not an invented traffic forecast.
You can review what is included and Elkwood's pricing. Owners who prefer to build directly can use the same checks with the 12-step AI website workflow.
Sources checked
Google JavaScript SEO basics, checked 26 August 2026.
Google crawlable-link guidance, checked 26 August 2026.
Google sitemap guidance, checked 26 August 2026.
Google canonical URL guidance, checked 26 August 2026.
Google structured-data guidelines, checked 26 August 2026.
Google people-first content guidance, checked 26 August 2026.
Google guidance on using generative AI content, checked 26 August 2026.
Google Web Vitals, checked 26 August 2026.
W3C Web Content Accessibility Guidelines 2.2, checked 26 August 2026.
Quick answers
Frequently asked questions
Can AI-built websites rank on Google?
Yes. They can rank when Google can crawl and render the site and the content is useful, relevant and competitive. AI assistance does not supply authority or remove normal technical requirements.
Does Google penalise AI-built sites?
Google's published guidance focuses on helpful output and spam behaviour, not a blanket penalty for AI assistance. Using automation to create large amounts of low value content for rankings may violate its scaled content policy.
Are AI website builders bad for SEO?
Not inherently. Many provide good standard controls. Problems arise when pages are difficult to crawl, generic, duplicated, slow, incorrectly canonicalised or published without technical review.
How do I test whether an AI website is crawlable?
Inspect the initial HTML, rendered DOM, links, robots controls, sitemap and HTTP statuses. Crawl the deployed domain and use Search Console URL Inspection for important pages.
Does JavaScript stop Google indexing a site?
No. Google can render JavaScript, but rendering is a separate stage and failures can hide content. Server rendered or pre rendered HTML reduces dependencies and is more accessible to crawlers that do not execute JavaScript.